Deepak Vijaykeerthy
I work on post-training language models and agents with reinforcement learning, and on the simulated environments those agents are evaluated and trained in. I was a Research Assistant at Microsoft Research India from 2013 to 2015 and have been at IBM Research since 2016. My work has appeared at AISTATS, SIGMOD, CVPR, UAI, AAAI and PLDI.
Email is the best way to reach me.
Current Research
Rollout generation is often the largest cost in RL post-training. With a group-relative baseline, a prompt contributes a direct gradient only when its rollouts disagree, so compute spent on prompts the policy always or never solves is largely wasted. The work below asks how to spend that compute where the policy can still learn.
GRPO-style recipes make several training decisions by fixed rule: uniform prompt sampling, a fixed number of rollouts per prompt, and a baseline and normalization computed from the current group alone. Most recipes keep no running estimate of what the policy can and can't solve, although that's what determines which prompts produce a gradient. Dynamic sampling and difficulty filters adjust which prompts are used, mostly from recent outcomes. Each batch of rollouts is also a measurement of the policy. We're building a persistent model of the learner from these measurements that informs the baseline, the weighting and the number of rollouts as well as sampling. This extends our earlier work on estimating a model's ability from a few test items (ICML 2024 DMLR), where the model being measured didn't change.
As the policy improves, a fixed task distribution stops producing useful training signal, so the environment has to change with it. We study this with search agents, where what the environment teaches matters as much as how hard it is. An agent that has found three affected customers can't tell from those records whether a fourth exists, so stopping is a bet on evidence it hasn't seen. Agents trained with outcome rewards tend to stop too early. Our hypothesis is that they learn the base rates of their training data. If the missing record is rare in training, stopping early is usually correct and saves search cost, so the reward favors it. We're studying how to build and adapt training environments so that stopping depends on the evidence the agent has gathered.
Evaluating an enterprise agent before deployment, or training it with RL, requires an environment that reproduces the coupled services and data stores it will operate on. Their state evolves between the agent's actions, and the agent's own actions condition what follows, so each episode has to be simulated online. Our premise is that fidelity is required only at the interface the agent acts through, since environments that respond identically to every available action are indistinguishable to it. Starting from a seed, we learn this interface from traces and realize each component behind it as a real system, a stub or an LLM simulation, depending on how much of it the agent can observe and how much other state depends on it. The central difficulty is keeping this hybrid consistent over long episodes, especially under RL, which will exploit any inconsistency that increases reward.
An agent's harness consists of its tools, what they return, its memory and how its context is managed. Harness changes can shift performance as much as further training, yet harnesses are usually designed by hand and kept fixed during training. Each component encodes an assumption about what the model needs, and the same component can help one model and hurt another. Building a strategy into a tool also removes the need for the model to learn it. Our hypothesis is that scaffolding works best as a temporary aid, added between rounds of RL where a model falls short and removed once it has learned the capability. What remains at the end would show which computation and state are better kept outside the weights.
Selected Publications
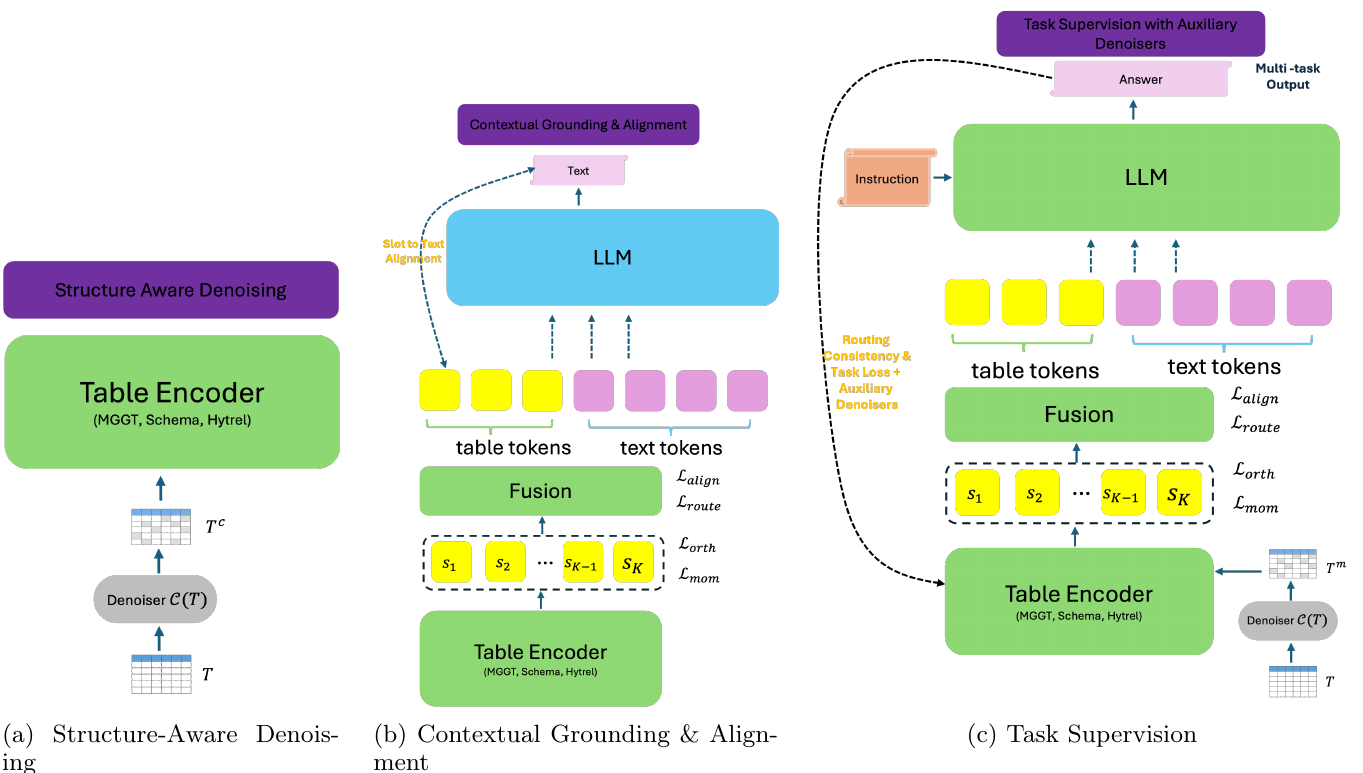
Serializing a table into text ties a model to surface details such as header wording and row order. Renaming columns or shuffling rows doesn't change a table's meaning, yet it causes large accuracy drops. We give tables their own encoder, pretrained on 3 million tables by reconstructing deliberately corrupted ones, and fuse it end to end with an 8B decoder-only LLM, in the way vision-language models handle images. Under row shuffling and header anonymization the model loses under 2 points, while the same architecture fine-tuned directly on the same data loses 6 to 22 points.
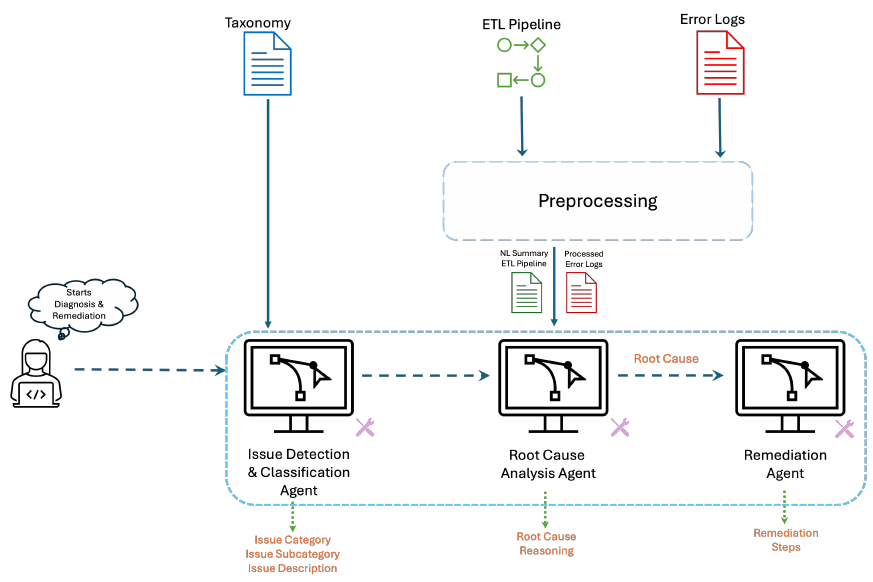
In an ETL pipeline, an error often surfaces well downstream of the stage that caused it. A zero divisor upstream becomes a NULL, passes untouched through a join, and only violates a NOT NULL constraint at the final write, where the error is reported. We built a multi-agent system that reasons backwards from symptom to cause. One agent classifies the failure against a practitioner-derived taxonomy, a second traces it upstream through the flow's structure and transformation logic, and a third proposes ranked remediations for the engineer to choose from. It runs in IBM watsonx.data integration on production DataStage pipelines.
- 2026DataBench: A Benchmark Dataset to Evaluate Agents for Data Pipeline RemediationRitwik Chaudhuri, Deepak Vijaykeerthy, et al. Benchmarks for data agents mostly ask them to build pipelines from a clear specification. Much of production work is repair, which is harder because the agent first has to infer what a broken pipeline was meant to do from its code and the log of a failed run. DataBench poses that problem directly. Each case injects one fault into a working pipeline or its data, and a fix counts only if the pipeline runs again and reproduces the correct output table. Across 86 such cases in nine fault categories, agents built on current state-of-the-art LLMs fix about 30%.Under review at KDD 2027
- 2024DMLR Workshop, ICML 2024
- 2022
- 2020
- 2020
- 2019
- 2015
Full list on Google Scholar and DBLP.
Experience
- IBM Research · Research Engineer · 2016 to presentI've run continued pretraining, SFT and RL on models up to 30B. Earlier I built foundation models for tabular data and LLM agents for data engineering, one of which shipped in watsonx.data integration. Before that I worked on fairness verification, explainability, adversarial robustness, test generation for ML systems and AutoML.
- Microsoft Research India · Research Assistant · 2013 to 2015I worked on synthesizing probabilistic programs from observation traces with MCMC (PLDI 2015).
Code
Post-training papers are usually organized by objective family. The choices that determine training behavior lie below that level, in which samples get gradient weight and at what granularity, how stale replayed data may be, and how far a proxy reward can be trusted. Methods from the same family can disagree on any of them. rl-experiments isolates these choices in PyTorch sandboxes small enough to read the gradient directly, so failures that take days to surface at scale show up on a single GPU.
- Group-relative RL gets a direct signal only from prompts the policy solves some of the time. Prompts it never solves give no signal yet, and prompts it always solves give none either. Pretraining, SFT, curricula, larger groups and distillation all bring tasks into that useful range, each by a different route, which is why they aren't interchangeable fixes for sparse reward.
- In our sandbox, GRPO's entropy collapse traces to the standard-deviation normalization. When a group nearly agrees, dividing by its spread inflates a negligible reward gap into a full-sized step. The clip only bounds the size of that step, so tightening it has little effect, and the variants that do slow the collapse, such as Dr. GRPO, change the normalization. Whether the same mechanism dominates in large-scale runs is the next thing to test.
- Assigning credit at a finer grain redistributes the signal a reward already contains and can't create signal where the reward is silent. Creating signal requires reward shaping.
minilab runs the whole stack, from pretraining through RLVR, on a single laptop GPU, with every RL method sharing one rollout loop, so each stage of post-training can be watched at a scale small enough to reason about. The research built on it treats sparse-reward RL as an information problem before an optimization problem, since an update can only reinforce a trajectory that the policy visits and the verifier can tell apart from the failures around it.
Notes
- How I think about the design space of post-training RLrl-experiments
- Reward contrast and the limits of group-relative RLlearnability sandbox
- Tracing GRPO's entropy collapse in a small sandboxrl-experiments
- When does verifier-guided RL help a small tool-using model?minilab